ARGONAUT LABS

INDEPENDENT SYSTEMS RESEARCH

Frontier-scale models
on one Mac.

We stream open models of 500 GB to 1.4 TB from SSD on a single MacBook Pro, and publish every run.

01 / SELECTED WORK

Three models. One line of inquiry.

How much further can better storage
and scheduling take one Mac?

01 / KIMI K308 SEP 2026

Trillion-parameter inference.
One 128 GB Mac.

1.94×

throughput with four SSDs vs one

Usage-weighted replicas and coordinated reads for a 2.8T-parameter model with 1.45 TB of expert weights.

128 generated tokens · drafting on
0.5350 → 1.0377 tok/s, inclusive

Explore Kimi results
02 / DEEPSEEK V4.127 SEP 2026

Start the expert reads
before the GPU is done.

+83%

steady decode vs upstream on the same single SSD, software only

Flag readback of the router’s expert ids, a larger expert cache and fused BF16 epilogues in our public fork of Antirez’s ds4 engine.

512 prompt / 200 generated tokens
10.18 → 18.66 tok/s on one SSD · output identical · 22.25 with two enclosures
30 Sep: prompt processing 45.50 → 68.09 tok/s on three drives, read-ahead staging
4 Oct: 68.67 → 73.16 tok/s, conditional read-ahead prior

Explore DeepSeek results
03 / GLM-5.3 FULL11 SEP 2026

Keep the GPU moving.
Shorten the wait.

+16.0%

vs the same four-drive engine control

Poll-gated pre-commit and a faster cache eviction scan, tested on the full 744B MoE model.

512 generated tokens · three matched pairs
3.46 → 4.02 tok/s, after first response

Explore GLM results

Each result has its own workload, timing definition and baseline. These are separate experiments, not a ranking of the models.

02 / THE APPROACH

More bandwidth helps.
Using it well matters.

The slowest required read can hold up an entire layer. We investigate where experts live, how reads are divided and how much useful work can happen while data arrives.

Read the DeepSeek implementation ↗
SSD 01Internal
SSD 02Enclosure A
SSD 03Enclosure B
COORDINATED EXPERT READSSplit the work. Join the results.

Divide reads across replicas; wait for the required pieces.

Cache + inference engineOverlap reads with useful compute
Conceptual expert-read path. Placement and scheduling policies differ by engine. DeepSeek Engram stays on the internal SSD.

03 / MEASURED RESULTS

The numbers, with their context.

M5 Max · 128 GB
Measured runs, documented conditions.

DeepSeek V4.1 Flash · 552B · 518 GB at 4-bit · one 128 GB MacBook Pro M5 Max

upstream ds4, internal SSD10.18our fork, same SSD18.661.83×+ 1 enclosure21.052.07×+ 2 enclosures22.252.19×

tok/s · 512-token prompt, 200 generated · medians of interleaved pairs · output identical to upstream. The first step is software only: same laptop, same single internal SSD. Hover or tap a bar for each step. Each model on its own scale; the grey bar is the reference the multipliers are measured against. Chart data and generator: argodrive/charts.

KIMI K3 / DELTAFIN

From one SSD
to four.

Nearly twice the throughput in the 128-token drafted test. The four-drive layout combines a full expert home with usage-weighted replicas.

Scaling report & raw evidence ↗
128 generated tokens · drafter on · inclusive tok/s
Expert storageThroughputVs one SSD
Internal only0.5350Baseline
Internal + one enclosure0.75961.42×
Internal + two enclosures0.93751.75×
Internal + three enclosures1.03771.94×

One run for the one-, two- and three-drive rungs; four-drive median of two. Layouts differ in replica coverage. Cross-layout output identity is not established. A separate 512-token prompt takes about 6.3 minutes to first token on four drives.

Longer generation and prefill measurements ↗
DEEPSEEK V4.1 FLASH Q4 / DS4

Prefill was reading one drive.
And twice the bytes.

A 518 GB model streamed from NVMe on a 128 GB laptop. Prefill went through the memory map of the primary file, so one drive moved 315.9 GB while the others sat idle — and the layer-major sweep read all 384 experts per layer where the prompt routes to 187. Staging every layer through the weighted split read, then reading only the selected experts. Measured against the pinned upstream binary with a byte-identical output hash on every arm.

ARGODRIVE — the layout, balancer and instruments ↑Method, every arm and raw data, 15 September →The 27 September stack, the drive ladder against upstream and the 28 September follow-up →Engine branch (fork of antirez/ds4) ↑
512 prompt / 200 generated tokens · one interleaved session, 27 September · upstream median of 6 arms, fork rungs median of two
MeasureUpstream, one driveOurs, one driveOurs, + 1 enclosureOurs, + 2 enclosures
Prompt processing17.9630.98 (1.72×)36.88 (2.05×)42.41 (2.36×)
Steady decode10.1818.66 (1.83×)21.05 (2.07×)22.25 (2.19×)
Generation incl. first step9.9017.45 (1.76×)19.54 (1.97×)20.74 (2.10×)

All four columns come from one interleaved session on 27 September: upstream, fork, upstream, fork… so every multiplier is against the same control measured minutes apart. Control is the pinned upstream ds4 binary bd66c402, the base this fork is built on, compiled with the same toolchain; every arm produced the same output SHA-256, so the comparison is like-for-like. The one-drive column needs no replicas at all — same laptop, same single internal SSD, same model file; it is the portable part of this result and it is software only. The enclosure columns add weighted split reads across byte-identical copies of the 518 GB file (prefill 10:5 and 10:5:5, decode 10:6 and 10:6:6). Fork arms run profile v41-stack-20260927 with 4,600 cached experts; upstream sizes its cache automatically (3,688). Steady excludes the first decode step; generation includes it; both exclude startup and prefill; The earlier rungs (15 to 19 September: 14.38 one drive, 18.45 three drives against a 10.6 control) and the 512/512 stack qualifications (20.30 → 22.74 against our own 21 September engine on 27 September; 22.92 → 23.26 on 28 September with a post-MoE flush and an eviction pre-scan) remain on the research pages.

512 prompt / 200 generated tokens · one interleaved session, 4 October · profile v41-stack-20261004 · fork rungs at a 3,600-expert cache · tok/s and multiplier against the same-session upstream
MeasureUpstream, one driveOurs, one driveOurs, + 1 enclosureOurs, + 2 enclosures
Prompt processing17.3047.71 (2.76×)62.99 (3.64×)75.06 (4.34×)
Steady decode10.1716.94 (1.67×)18.64 (1.83×)19.31 (1.90×)
Generation incl. first step9.8016.29 (1.66×)17.83 (1.82×)18.56 (1.89×)

4 October, prefill. The 30 September read-ahead staging plus a continuous prefill reader, Engram row-table reads on upstream’s prefetch thread from the first layer, and a conditional read-ahead prior (how often an expert at one layer followed each expert of the previous layer in 19 other prompts, applied to this prompt’s own routing). Qualified against the 30 September binary at +6.4% (512/512) and +6.5% (512/200), both sides at a 3,600-expert cache, output byte-identical on every arm. The three-drive prefill is drive-bound (the lanes read 177 GB per 512-token prompt at the 25.5 GB/s three-drive ceiling), so only read-ahead precision moves it. Qualification package · Ladder package · Release

512 prompt / 200 generated tokens · one interleaved session, 30 September · profile v41-stack-20260930 (prefill read-ahead) · fork rungs at a 3,600-expert cache · upstream median of 6 arms, fork rungs median of 2
MeasureUpstream, one driveOurs, one driveOurs, + 1 enclosureOurs, + 2 enclosures
Prompt processing16.1243.75 (2.71×)58.13 (3.61×)68.29 (4.24×)
Steady decode10.1116.77 (1.66×)18.67 (1.85×)20.02 (1.98×)
Generation incl. first step9.7316.15 (1.66×)17.89 (1.84×)19.22 (1.98×)

30 September, prefill. Read-ahead staging fetches the next layer’s likeliest experts while the GPU computes the current one, ranked by a hotlist built from other prompts, and the routed MoE runs in two waves around the remaining reads. Qualified against the 28 September binary in the same session: 45.55 → 68.59 prompt tokens/s at 512/512 (+50.6%) and 45.50 → 68.09 at 512/200 (+49.6%), decode unchanged, output identical on every arm. The ladder above used a 3,600-expert cache and the qualification 4,200, because the 4,600 champion cache tripped the swap-growth guard on a machine that had not been rebooted; decode rungs are therefore below the 27 September table, which remains the decode reference. Qualification package · Ladder package.
GLM-5.3 FULL / DS4

744 billion parameters.
Four SSDs.

Three interleaved pairs at each length test pre-commit scheduling and cache eviction changes. Both sides retain the same four-drive split reads and prefetch.

GLM experiment, conditions & data ↗
11 September campaign · decode after first response
Generated tokensControlCandidateGain
1283.664.21+15.1%
5123.464.02+16.0%

Tok/s, medians of three runs per setting; matched output hashes across each six-arm group. Q4_K routed experts, 24-token raw financial prompt. Control is the same patched engine with the two changes disabled—not stock ds4. A 12 September candidate-only recheck measured 3.86 tok/s at 512 tokens.

04 / FROM RESEARCH TO PRODUCT

Meet ARGODRIVE.

The Mac workspace for understanding your drives,
inspecting inference runs and comparing what changed.

Download Mac beta ↗

Apple silicon · v0.2.0-beta.3

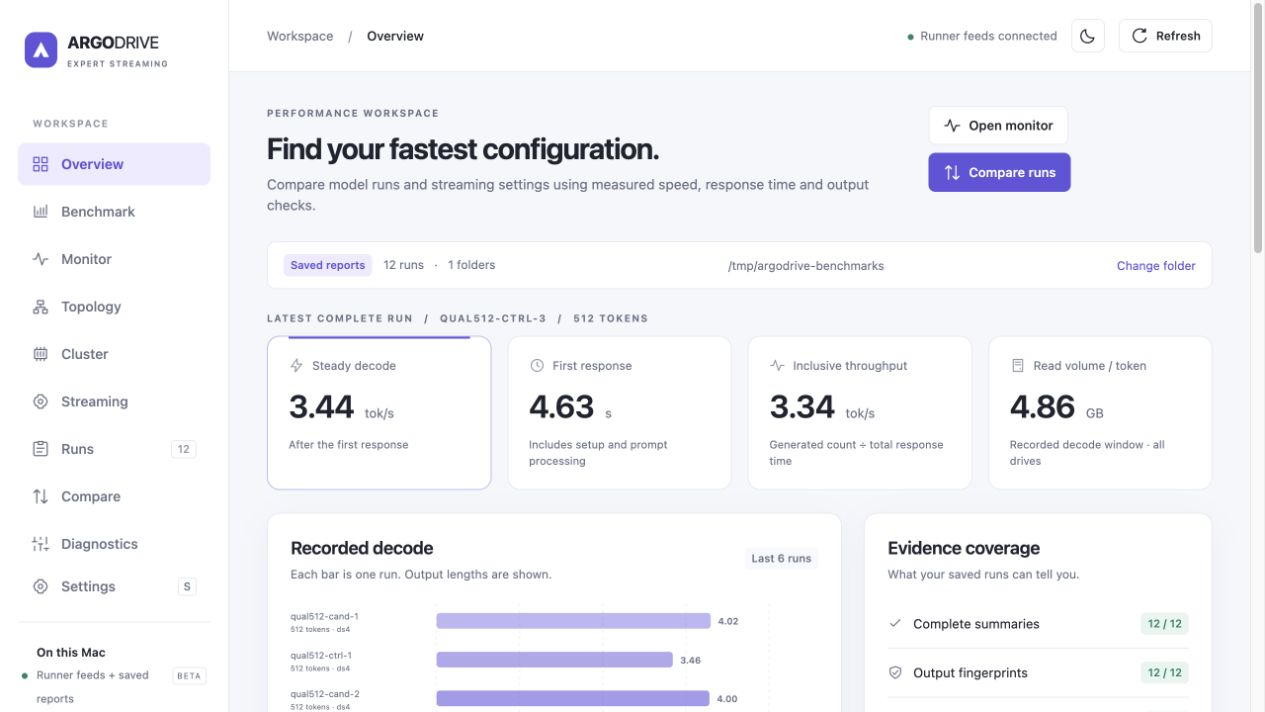
Real Argodrive workspace reviewing twelve recorded GLM qualification runs, with throughput charts, timing metrics and evidence coverage.
Argodrive workspace reviewing saved GLM qualification runs. Recorded results, not a live test.
01

See the activity.

Inspect drive reads, memory and the storage setup behind a run.

02

Compare the evidence.

Review saved measurements, output fingerprints and configuration changes.

03

Share what you learn.

Export results and report setup issues or findings on GitHub.

05 / ARGONAUT LABS

Independent research.
Work you can inspect.

We investigate storage, memory and scheduling for large-model inference on local hardware. Argodrive grew out of these experiments: a way to see the bottlenecks, compare changes and keep the evidence.

Our work builds on Salvatore Sanfilippo’s ds4 and gavamedia’s deltafin, and the wider llama.cpp and GGML ecosystem. Development and review use Claude, ChatGPT and OpenAI Codex, with human direction and measured validation.

Read the credits ↗